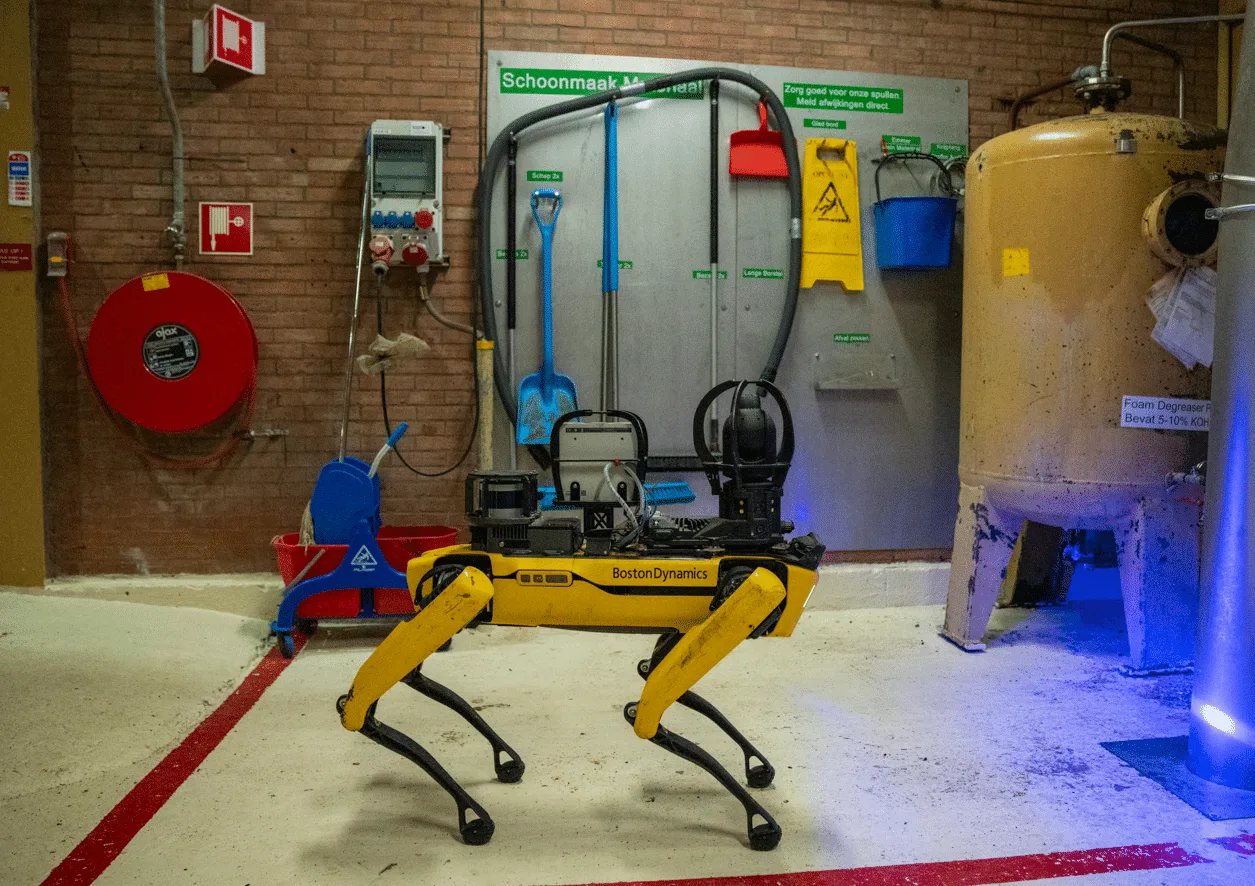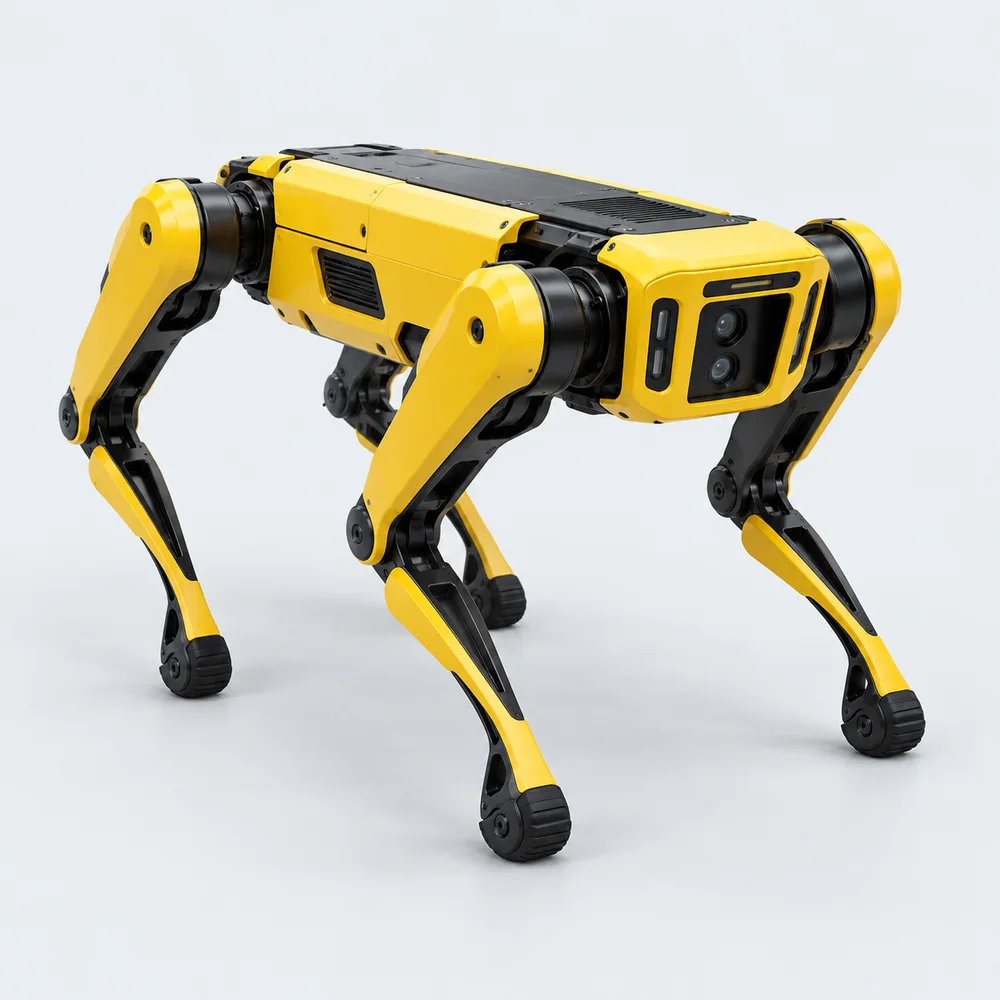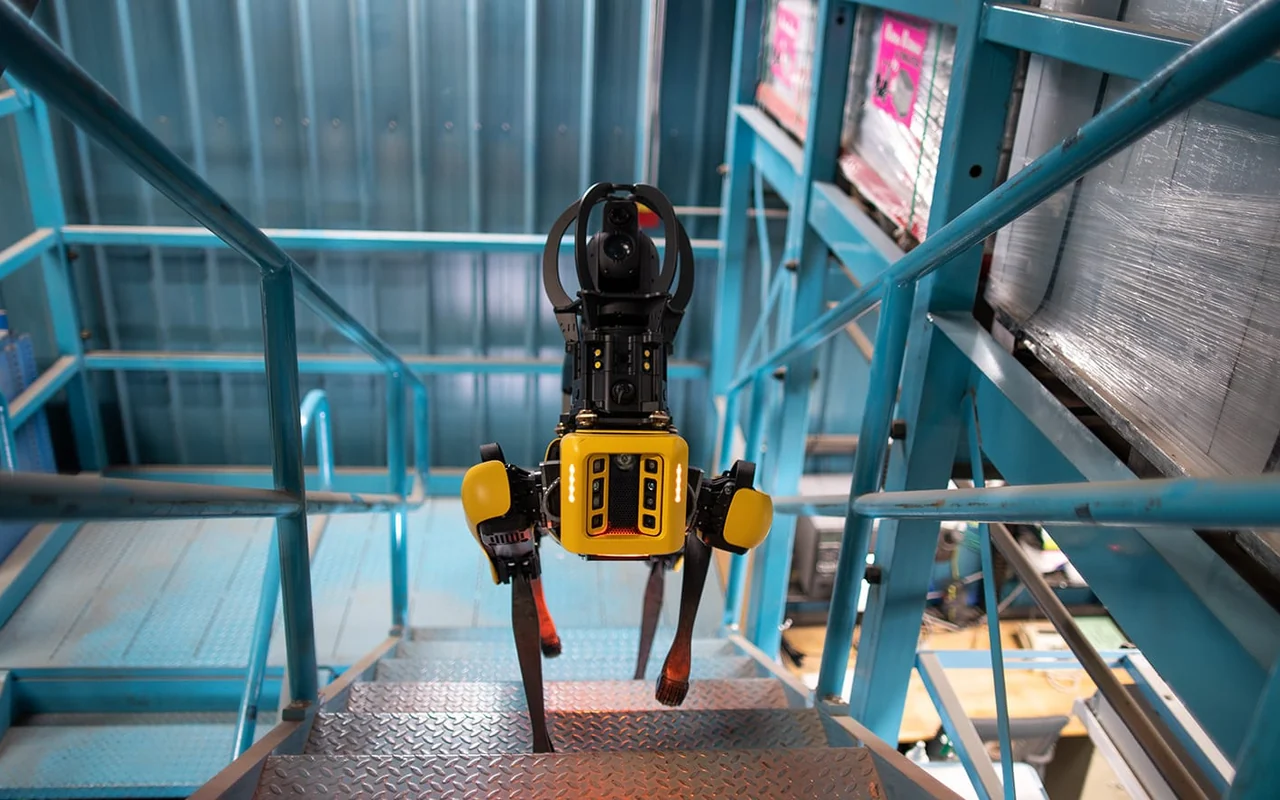
Boston Dynamics, together with Google Cloud and Google DeepMind, integrated Gemini and Gemini Robotics-ER 1.6 models into AIVI-Learning—the visual inspection module of the Orbit platform, which manages Spot robots. DeepMind introduced the new model version on April 14, 2026, and Boston Dynamics clients with AIVI-Learning have had access since April 8.
Gemini Robotics-ER is an “embodied reasoning” model: it handles spatial understanding, task planning, and result verification. When needed, the model autonomously calls tools—Google search, vision-language-action models, or user-defined functions.
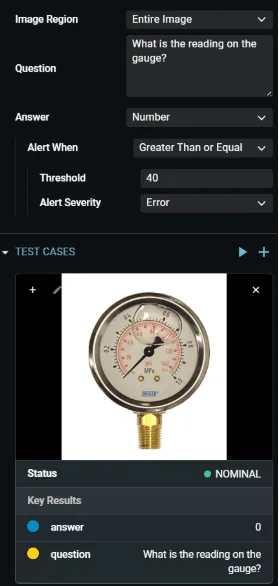
The main innovation is gauge reading, developed by DeepMind with Boston Dynamics. Spot circles the site, photographs gauges, level meters, and digital displays, and the model determines the readings. It zooms in on image fragments, marks points on needles and scales, calculates proportions, and accounts for units—even to sub-division accuracy.
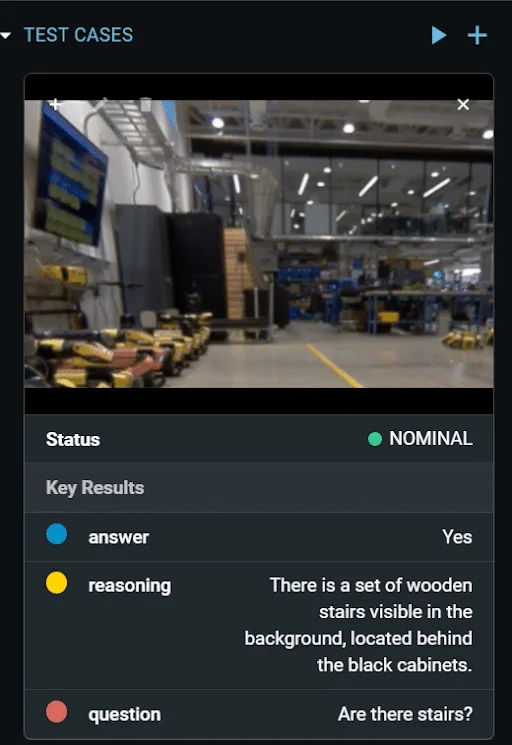
In practice, this covers occupational safety tasks—detecting hazardous debris and spills, monitoring conveyor belt damage, checking sight glass fill levels from 0 to 100%, counting pallets, and auditing order by the 5S system. Model responses now show the reasoning chain, and updates are delivered from the cloud without downtime. To use AIVI-Learning, clients must allow data transfer for model training.
Next, Boston Dynamics promises alerts for spills and unauthorized people directly on the site map. For industrial inspection customers, this means new inspection types can be added by configuring a query, not by separate development. Note that these features operate via cloud servers and require data exchange with the manufacturer.